Sticking a Package Cache in Front of My New AI Boxes
I have a habit of telling myself a job is going to be quick. It almost never is, and you'd think after this many years I would have learned to stop saying it out loud. But I keep doing it, because every so often a job actually is quick, and that one time is enough to keep the lie alive.
This was not one of the quick ones.
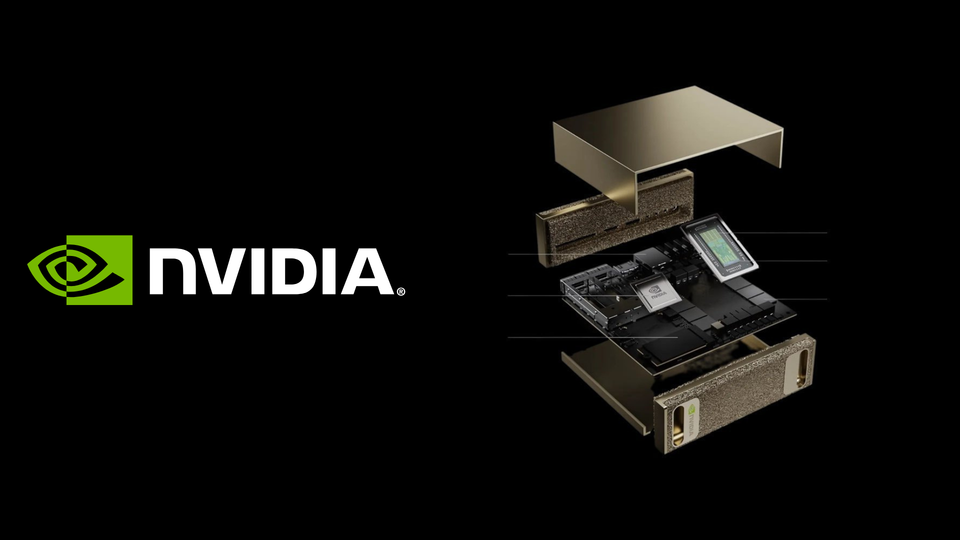
I picked up a pair of NVIDIA GB10 "Grace Blackwell" AI workstations recently. They're those little desk-side boxes that ship with DGX OS, which underneath all the NVIDIA branding is just Ubuntu 24.04 running on arm64. Two of them, sitting on the same subnet, and both of them about to reach out to the internet and pull down the same tens of gigabytes of CUDA, drivers, and the HPC SDK. Separately. Twice.
That bugged me before I even finished plugging them in. I already run apt-cacher-ng for the rest of my Ubuntu machines, so the fix was obvious. Put the cache in front of both boxes, let the first one prime it, and the second one pulls from the first instead of dragging it all down again. An afternoon, tops. I said it out loud. You already know how that went.
First, find out what these things actually talk to
I didn't want to assume what DGX OS pulls from. I wanted to see it. So on one of the boxes I dumped the actual source list:
tail -n +1 /etc/apt/sources.list /etc/apt/sources.list.d/*.sources 2>/dev/null
DGX OS wires in a lot more than a stock Ubuntu install. On top of the normal Ubuntu ports mirror, there's a whole stack of NVIDIA sources: CUDA at developer.download.nvidia.com, the DGX base OS and Spark repos at repo.download.nvidia.com, AI Workbench at workbench.download.nvidia.com, a handful of Canonical PPAs at snapshot.ppa.launchpadcontent.net, and Ubuntu Pro ESM at esm.ubuntu.com.
Then I caught the exact hosts apt reaches out to during an update, while the box was still going direct:
sudo apt-get -o Debug::Acquire::https=true update 2>&1 \
  | grep -oE 'https?://[^ ]+' | awk -F/ '{print $1"//"$3}' | sort -u
And that's where the first real detail showed up. Out of that whole list, exactly one repo is plain HTTP. Everything else is HTTPS. That one fact ends up deciding how the entire rest of the build works, so hang onto it.
Why HTTPS makes caching annoying
apt-cacher-ng caches plain HTTP without complaint. It sees the request, grabs the file, keeps a copy, hands it to the next box that asks. Simple and boring, which is what you want.
HTTPS is where it gets fussy, and for a good reason. A TLS session between the client and the origin is supposed to be a sealed tube that nothing in the middle can read. That's the whole point of it. So a cache sitting in the middle can't see the file going by, which means it can't store it. You get two ways around that.
The first is a remap. You tell apt-cacher-ng about the real backend, and you have the clients talk to the proxy over plain HTTP. The proxy does the HTTPS leg out to the actual origin itself, and it caches what comes back. This is the one that actually gets you caching on a third-party HTTPS repo.
The second is a passthrough tunnel. The proxy opens a straight CONNECT tunnel out to the origin and just gets out of the way. The TLS stays sealed end to end, which is great, but nothing gets cached, because the proxy never sees inside the tube. It's just a pipe.
I wanted caching on the big NVIDIA repos, so those get remapped. That lives in /etc/apt-cacher-ng/nvidia-dgx.conf:
Remap-nvdeveloper: http://developer.download.nvidia.com ; https://developer.download.nvidia.com
Remap-nvrepo:      http://repo.download.nvidia.com ; https://repo.download.nvidia.com
Remap-nvworkbench: http://workbench.download.nvidia.com ; https://workbench.download.nvidia.com
Remap-nvppa:       http://snapshot.ppa.launchpadcontent.net ; https://snapshot.ppa.launchpadcontent.net
Then on the client side you flip those sources from https to http so they route through the remap.
Now, the second you tell somebody you're turning an HTTPS repo into HTTP, they get twitchy, so let me head that off. apt does not trust a repo because of the transport. It trusts it because of the GPG signature on the repo metadata, checked on the client against the vendor keyrings listed in each source's Signed-By: line. Dropping the client-to-proxy hop down to HTTP doesn't touch any of that. The packages are still signed, they're still verified, and the leg from the proxy out to NVIDIA is still real, cert-checked HTTPS. The only cleartext is riding around on your own LAN. It's fine. Nobody is sneaking a poisoned CUDA package past a signature check.
The one repo you leave alone
esm.ubuntu.com is the odd one out, and it's worth understanding why before you go remapping everything in sight. Ubuntu Pro ESM is authenticated per machine. When you attach a box to Pro, it gets its own credential token dropped into /etc/apt/auth.conf.d/, and apt hands that token over to prove that particular machine is entitled to the content.
You do not want to remap that. Remapping would send that per-machine credential to the proxy in the clear and tear open the end-to-end TLS that's carrying it. And even if none of that bothered you, caching it would be pointless anyway. The entire reason a cache earns its keep is that two boxes ask for the same file and the second one gets it for free. Entitlement-gated content doesn't give you that. So ESM gets tunneled and never cached:
PassThroughPattern: esm\.ubuntu\.com:443$
The box still points at the proxy for it. The proxy just forwards it along without looking inside. Two lanes, and each repo goes in the right one. Cache the public stuff, tunnel the private stuff, everybody's happy.
That was the whole design. Clean. I was pretty pleased with it. And then it didn't work at all, which is the part that actually taught me something.
The proxy couldn't reach the repos
Before I pushed any of this live, I ran a plain reachability check from the proxy out to all the upstreams. First run, some hosts answered and some timed out. Second run, a different set answered and a different set timed out. One host threw a TLS certificate error out of nowhere. It had that flaky, intermittent, comes-and-goes feel that makes you immediately assume the firewall team is elbow-deep in a change somewhere and you just happened to test in the middle of it.
I very nearly wrote it up exactly like that and went to bed. Then I actually looked at which hosts were passing, and what they'd resolved to.
esm.ubuntu.com      -> 2001:67c:...   (IPv6)   OK
ports.ubuntu.com    -> 2620:2d:...    (IPv6)   OK
developer.nvidia... -> 23.221.x       (IPv4)   BLOCKED
snapshot.ppa...     -> 185.125.x      (IPv4)   BLOCKED
Every host that worked went out over IPv6. Every host that failed went out over IPv4. That's not some destination getting picked on. That's the box quietly splitting traffic by address family. The Ubuntu hosts had AAAA records and slipped out over v6 without me asking. The NVIDIA CDN resolved to v4 and walked straight into a wall.
Great, I thought, it's a v4-versus-v6 egress thing, and I started drifting toward a firewall request for the v4 hosts. And I was still wrong. Because the next test, where I forced each family on purpose, showed the hosts that had been working a minute ago were now failing on both families too. A host that answers twice and then goes dark isn't being filtered by where it lives. Something in the path is moving underneath me while I test.
The thing that finally cracked it was boring, which is usually how it goes:
ip -6 route show default # returned nothing
There was no IPv6 default route on the box. There had been one earlier. It was a router-advertised default, the SLAAC kind, and it comes with a lifetime attached. While it was fresh, v6 egress worked and the Ubuntu hosts happily went out that way. When the advertisement lapsed and nothing refreshed it, the route just quietly evaporated, everything fell back to IPv4, and IPv4 on 443 was closed. That whole "intermittent" song and dance was nothing but the v6 route blinking in and out between my test runs.
None of it was a flaky firewall. It was a box leaning its whole weight on a temporary route it had no business trusting in the first place.
Making it stop relying on IPv6
For a package cache, quietly depending on a route that shows up and disappears on a timer is exactly the wrong thing. I wanted it to use IPv4 and mean it, every single time. The cleanest way to do that without tearing IPv6 off the box entirely is one line in /etc/gai.conf:
precedence ::ffff:0:0/96 100
That's the standard RFC 3484 knob that shoves IPv4-mapped addresses to the top of the sort order that getaddrinfo hands back. After that, curl, apt, and apt-cacher-ng all resolve a dual-stack host to its v4 address first. IPv6 still works, it just stops getting first pick. You can confirm it with:
getent ahosts developer.download.nvidia.com | head
The v4 addresses should be sitting on top. And if you want a second lock on the door, apt-cacher-ng has its own switch, ConnectProto: v4, that pins the daemon itself to IPv4 for upstream connections no matter what the rest of the system decides to do.
Once every test agreed with itself run after run, the actual root cause finally stood up, and it was about as unglamorous as it gets. This proxy sits behind a locked-down egress policy on purpose. It had HTTP on port 80 to the Ubuntu mirror open, and basically nothing else allowed outbound on 443. A quick check against an unrelated HTTPS host confirmed it, no general outbound HTTPS at all. The IPv6 flapping had spent twenty minutes hiding a problem that turned out to be nothing more exotic than "those destinations were never allowed out."
So the last real step wasn't clever in the slightest. Get outbound IPv4 on 443 opened to the five repo hostnames, and do it by name, not by IP. They're all sitting behind CDNs, and the addresses they resolved to changed on me between nearly every test run, so pinning IPs would basically guarantee the rule breaks itself the next time DNS reshuffles.
What I'm keeping from this one
A few things I want future-me to remember, since past-me clearly needed them.
Get the ground truth before you touch any config. Dumping the real source list and the actual hosts apt talks to took about two minutes and quietly shaped every decision after it.
Sort your repos before you write a line. Third-party HTTPS repos need a remap if you want them cached. Authenticated repos need a passthrough and should never be cached at all. Know which lane each one belongs in first.
Treat "intermittent" as a clue, not an answer. A result that changes between two identical commands almost always means something in the path is moving. A route, a lease, a pair of mismatched egress boxes taking turns. It hardly ever means your config is subtly wrong, even though that's the first place your brain wants to go.
Look at the routing table early, not late. ip -6 route show default coming back empty would have saved me the entire address-family goose chase if I'd just run it up front.
And the big one. A dual-stack box that quietly prefers IPv6 will cheerfully hide an IPv4 hole in your egress, right up until the v6 path drops out from under it. If you need a box to be predictable, make it predictable on purpose. Don't leave it to drift and hope.
The build itself is tiny. Remap the public repos, tunnel the private one, force v4, done. Almost all the time went into a network fault that had nothing to do with apt-cacher-ng and everything to do with me believing the first tidy story that came along. Which, if I'm honest, is how most of my "quick" jobs go.
Comments ()